
Turning engagers on your own LinkedIn posts into meetings
Anyone who likes or comments on your own LinkedIn post is already a warm lead. The concrete playbook, shown live on a real Proseller example: table columns, sequence design, real numbers.
Not the wider feed — your own post
LinkedIn keyword monitoring watches the entire feed for buying signals around specific terms — anywhere on LinkedIn, regardless of who posted. This playbook is narrower and therefore warmer: it takes only the people who reacted to your own posts — likes, comments — and turns them into an outreach list. No guessing about interest: the person has already commented publicly on exactly the topic you are posting about.
The example below is a real, running implementation at Proseller AG — including the numbers it actually produces, not the ones anyone hoped for.
Step 1: Set up the engager table
The starting point is a table with a source that collects post reactions: for every new post by the sender, likers and commenters are automatically added as new rows. At Proseller this runs on posts by “Alfred Rossi” (the company’s LinkedIn sender persona) — after several weeks of runtime the table behind it has collected 4,185 rows.
The column structure that turns raw data into contactable leads:
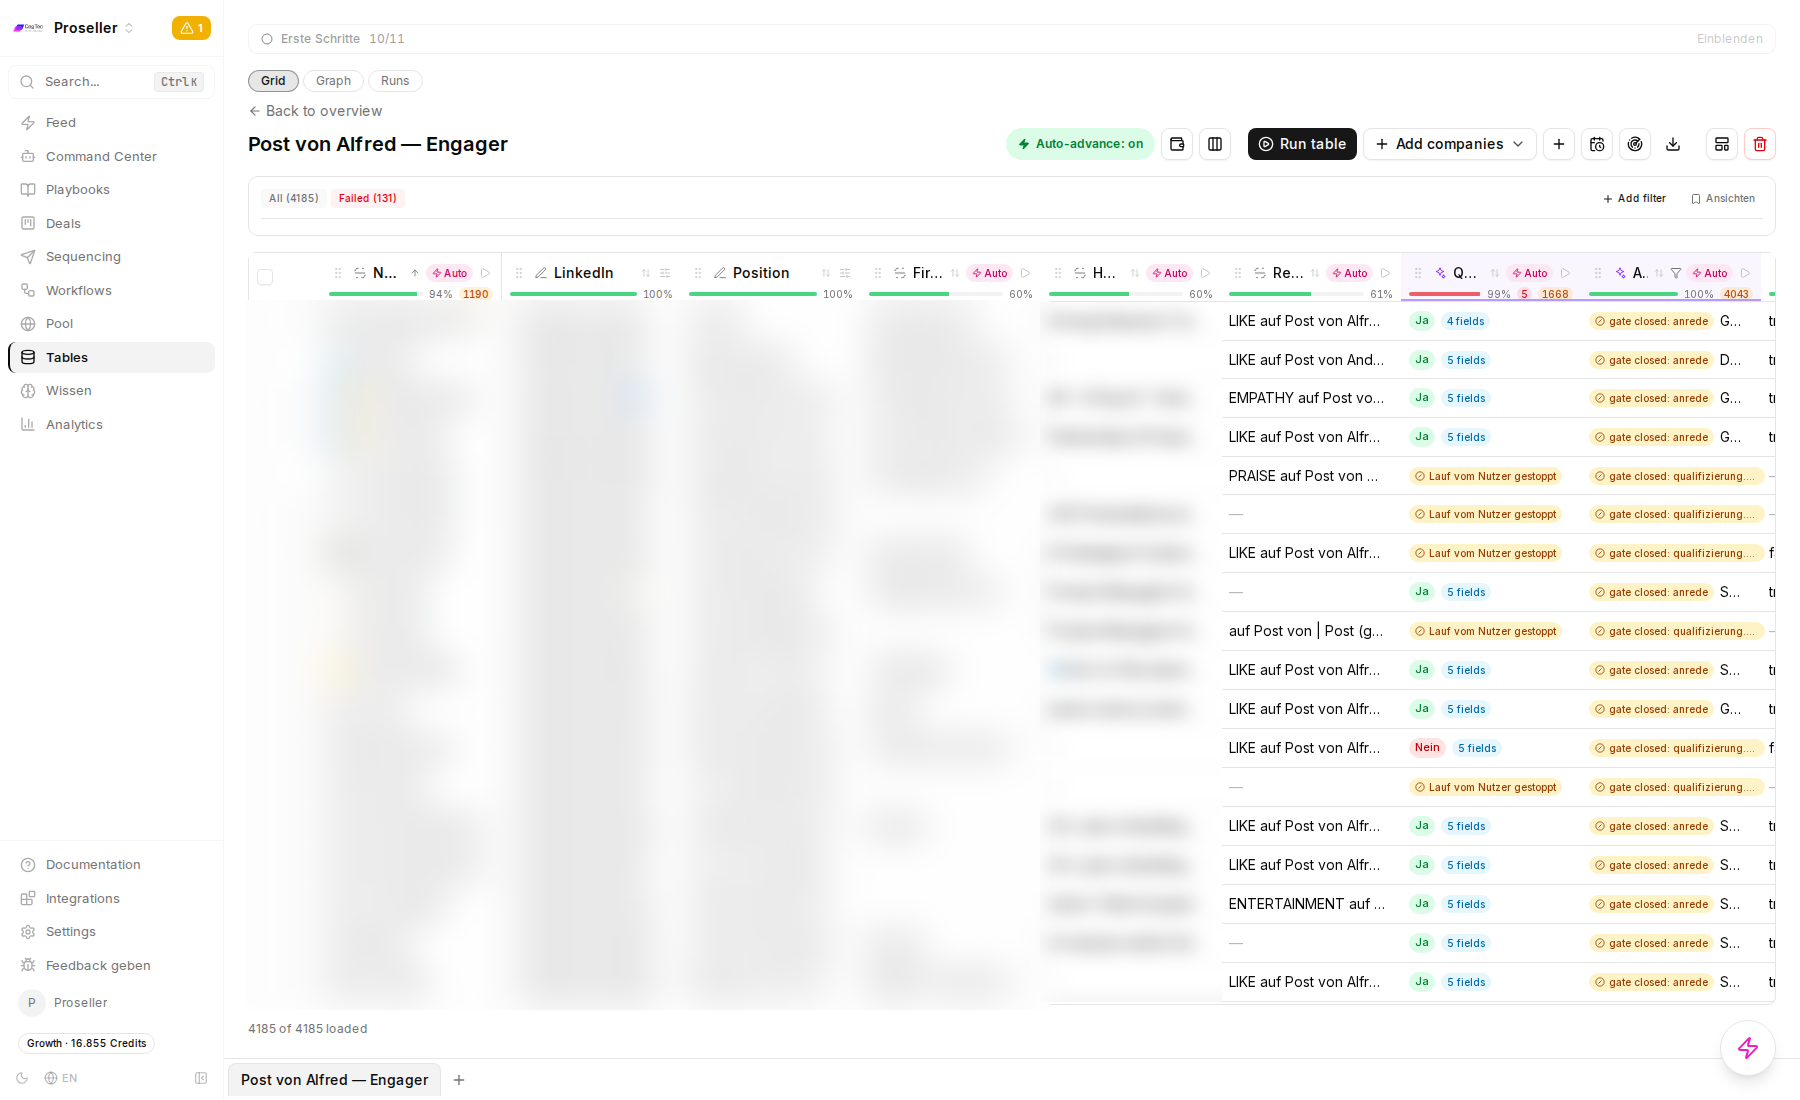
- Name, LinkedIn, position, company, headline — resolved automatically from the LinkedIn profile as soon as the reaction arrives.
- Reaction + post — records what the person did and what to: “LIKE on post by Alfred…”, “EMPATHY on post by…”, “PRAISE on…”. At Proseller all four LinkedIn reaction types (like, praise, empathy, entertainment) actually occur — this is the preserved context that later carries the opener.
- Qualification — an AI column that checks position, company and headline against the ICP and states in plain language why yes or no.
- Salutation — automatically generates the correct form of address from the resolved name.
- Qualified? — the binary gate (yes/no) that decides whether a row may enter the sequence at all.
- Intent, total score — additional weighting if you want to prioritise beyond a plain yes/no.
- Enroll — the terminal column: only running it actually writes the row into a sequence. Nothing happens automatically before that.
A practical note from real use: of 4,185 sourced rows, 131 are marked “failed” — enrichment fails on some profiles (private profile, deleted account, unresolvable company). That is normal, not a misconfiguration.
Step 2: The sequence — a graph, not a rigid list
The outreach itself runs as a graph rather than a linear step list — that allows conditions (already connected? already replied?) instead of forcing the exact same chain on everyone.
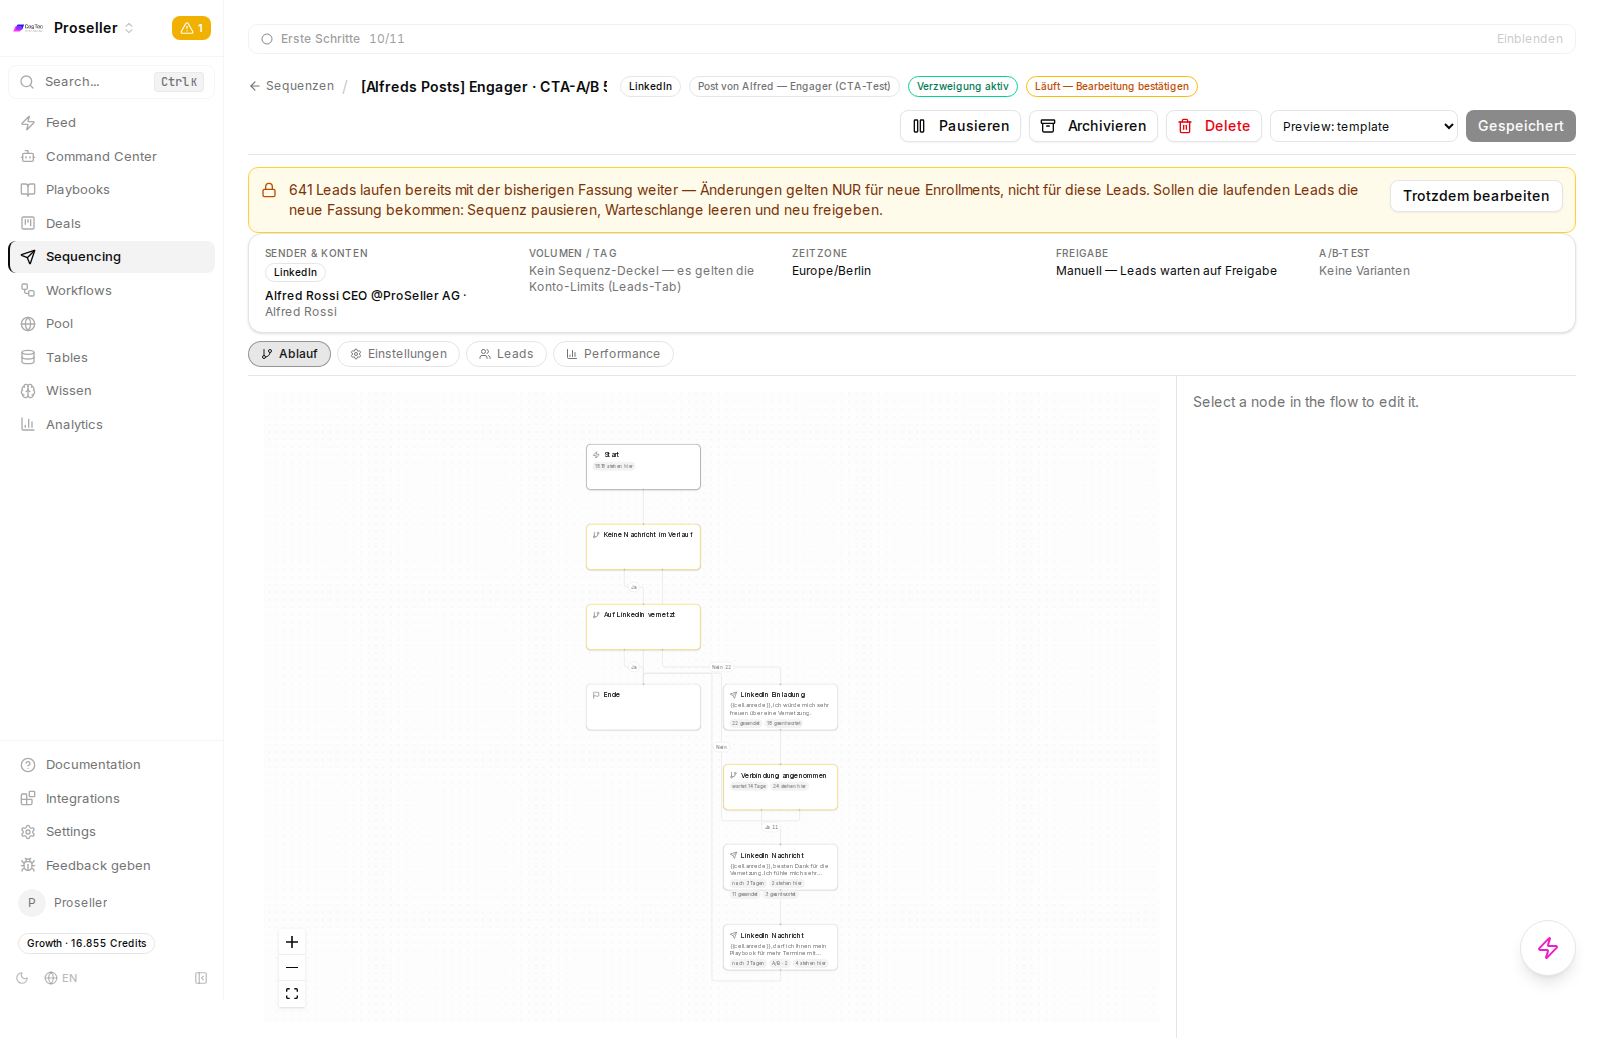
The Proseller flow, node by node:
- Start → condition: “no message in thread”. Anyone already contacted is not processed twice.
- Condition: “connected on LinkedIn”. Existing connections go straight to step 3, everyone else gets an invitation first.
- LinkedIn invitation without a note — a higher acceptance rate than an invitation with text.
- Condition: “connection accepted” — with a 14-day window. Not accepted within that window means: stop, no further touch.
- Thank-you message after acceptance, referencing the connection.
- CTA message — this is where the A/B split runs (next section).
Step 3: Test CTAs against each other, but take the sample size seriously
Two CTA variants ran against each other: a playbook offer versus an “AI sales agents” introduction.
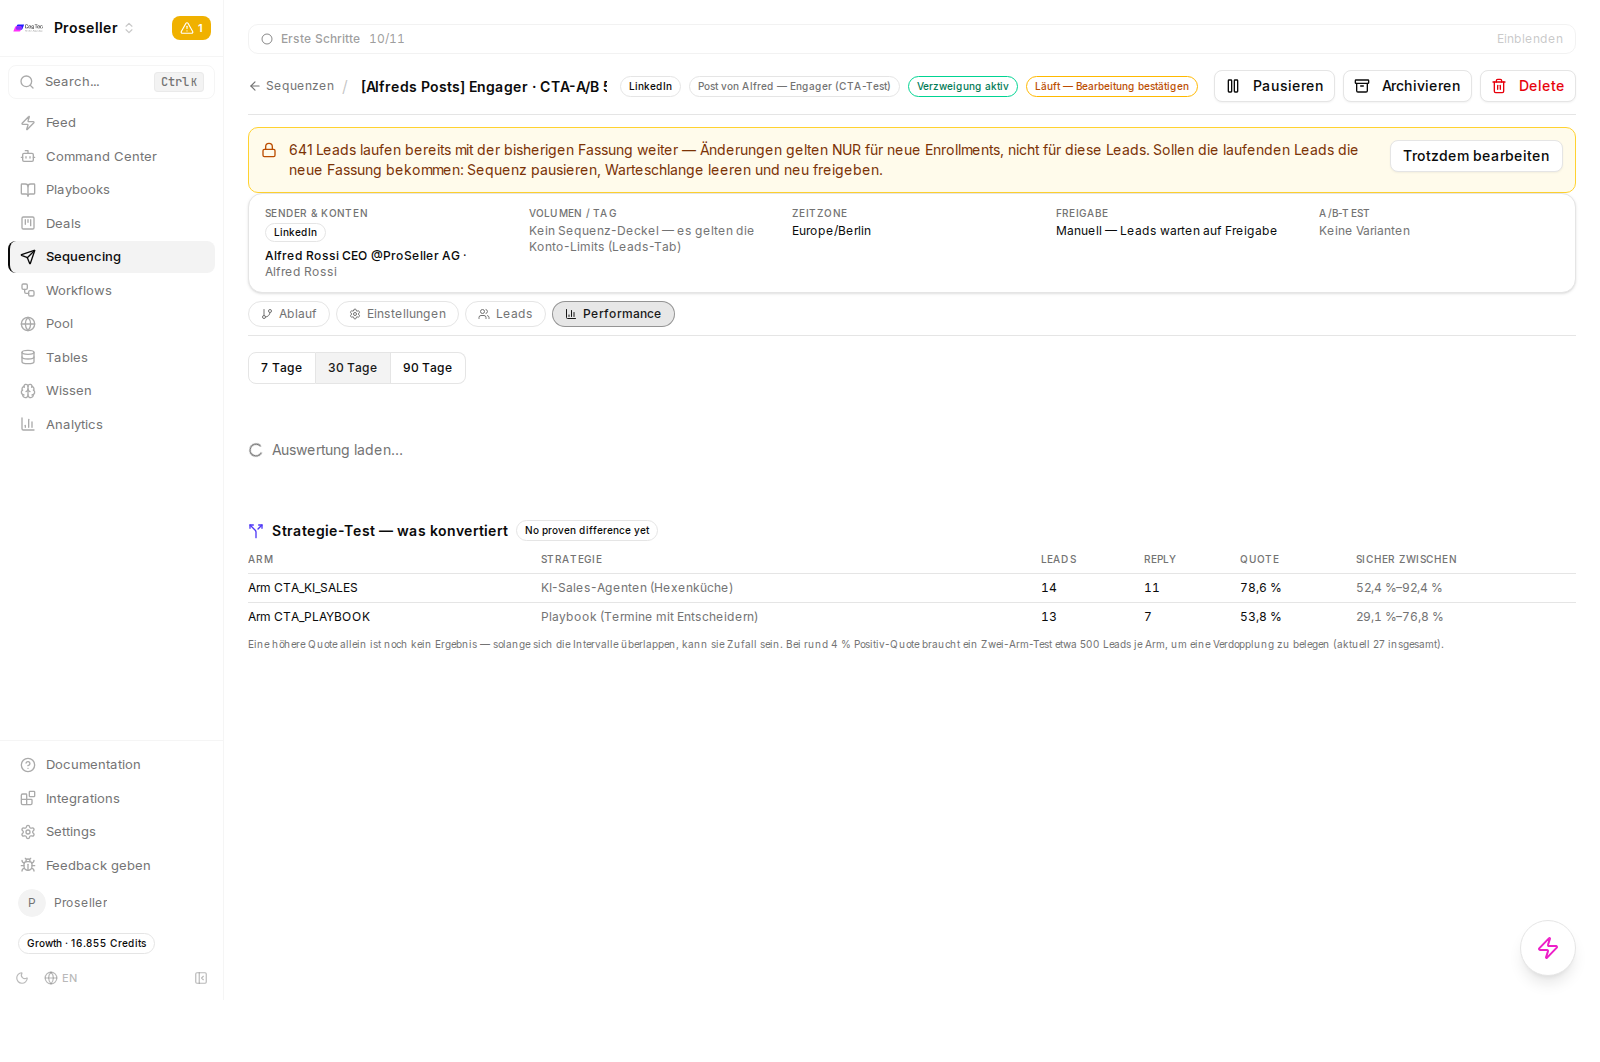
| Variant | Leads | Replies | Rate | Confidence interval |
|---|---|---|---|---|
| AI sales agents | 14 | 11 | 78.6 % | 52.4–92.4 % |
| Playbook offer | 13 | 7 | 53.8 % | 29.1–76.8 % |
The product itself flags the result as “No proven difference yet” — rightly so: when confidence intervals overlap, the higher rate is not yet proof and may be chance. The tool’s own estimate: to statistically demonstrate a doubling from a baseline of roughly 4 %, a two-arm test needs about 500 leads per arm — here 27 had run in total at the time of evaluation. The lesson: an A/B test with a few dozen leads is a first directional signal, not a verdict. Only at several hundred leads per arm does the rate become reliable.
What actually comes out at the end
The 30-day aggregate across the whole sequence, not just the A/B test:
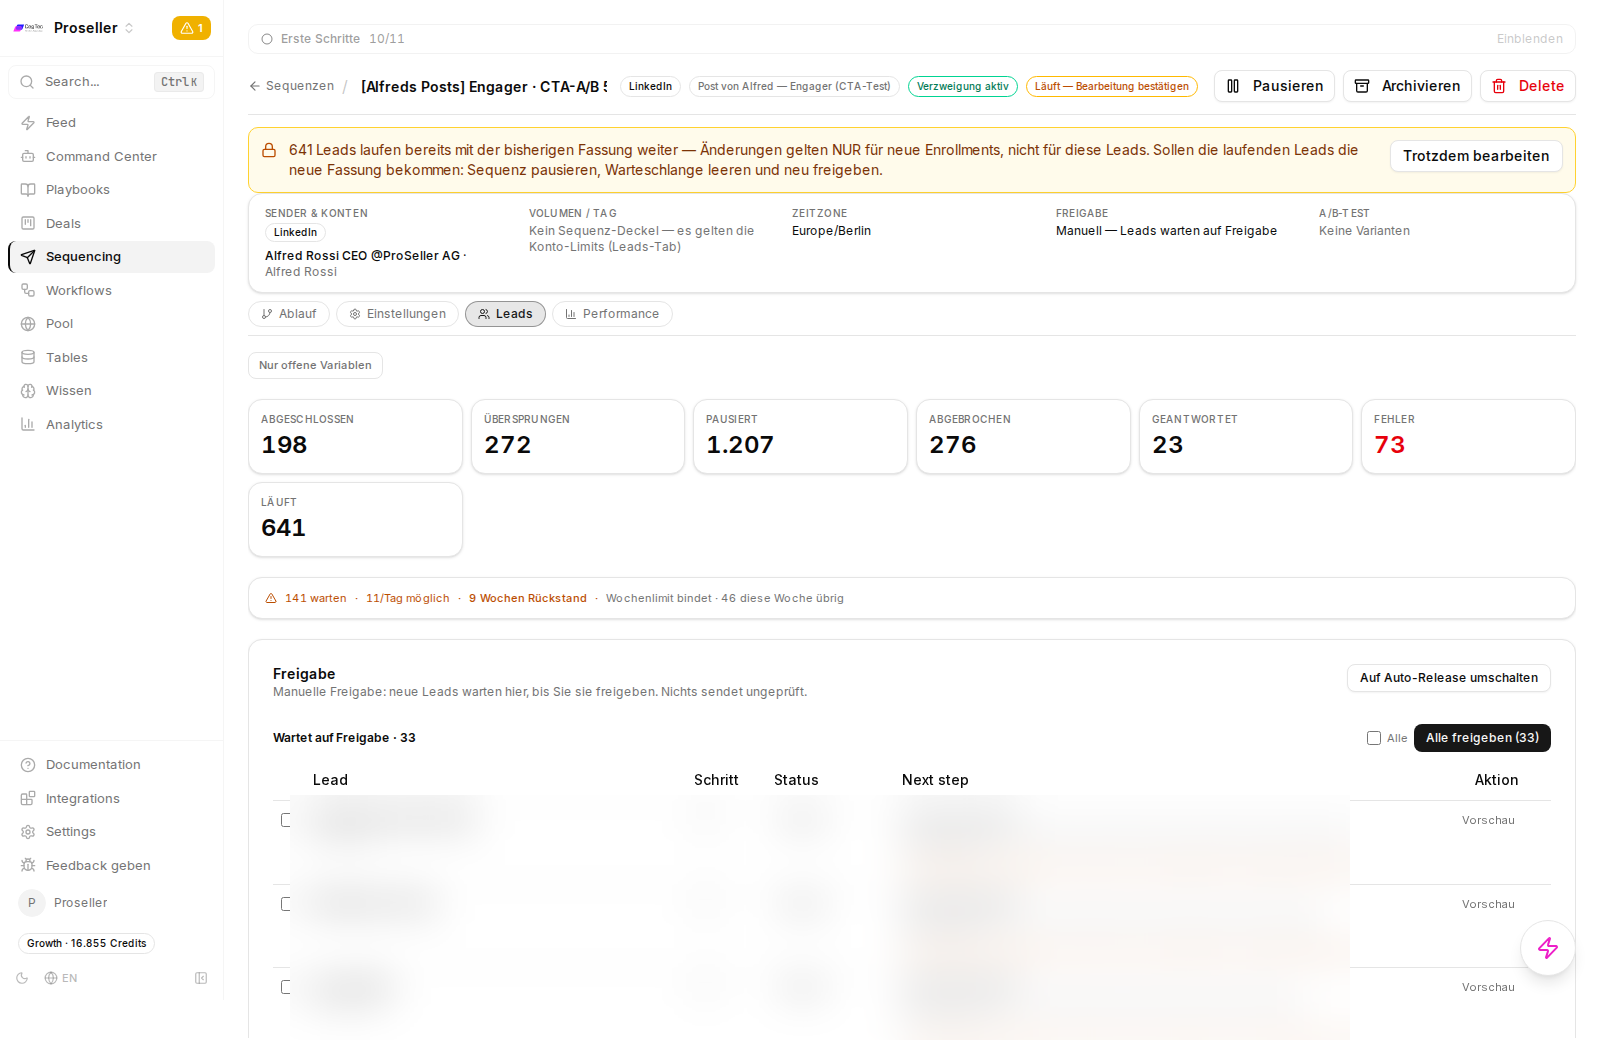
- 2,690 leads have run through the sequence in total, 641 are currently still running on the previous version.
- Over the last 30 days: 63 first contacts, 22 replies — a reply rate of 34.9 %, of which 17.5 % positive.
- Conversion per node shows where the rate actually comes from: the LinkedIn invitation itself achieves a 31 % reply rate across 58 sends; the thank-you message after it only 16.7 % across 18 sends. The strongest lever sits at the start of the chain, not at the end.
- 73 errors and 548 stopped leads are part of normal operation, not an outlier — LinkedIn automation has a real error rate (declined invitations, withdrawn profiles, rate-limit throttling).
For context: that is well above the cold LinkedIn baseline of 26.2 % (see the keyword monitoring playbook) — and a different picture from the Proseller signal playbook at 13 %, which searches the whole feed by keyword rather than targeting reactions to your own posts. The closer the signal sits to your own content, the higher the rate appears to be — but here too: a single sequence at one client is an example, not statistical proof across industries.
The built-in safety brake: manual release
Before anything is sent, a hard gate sits in between: “Manual release: new leads wait here until you release them. Nothing sends unchecked.” In the screenshot above, 33 pre-written messages are waiting for visual review, with a plain-text preview of every single message before a click releases it.
One concrete error the release view surfaces itself: “Unresolved placeholder in step text: {{cell.anrede}}.” That means the salutation column was empty for this row, or the run stalled at that point — without the manual check, a message would have gone out showing a literal {{cell.anrede}} instead of a real salutation. That is exactly why the brake exists.
Plan for rate limits honestly
The queue also shows the real capacity ceiling: 141 leads waiting, 11 per day possible, 9 weeks of backlog, the weekly limit being the binding constraint, 46 left this week. That is not a software fault but LinkedIn’s own limit on connection requests per account and day. Anyone setting up this methodology should plan from the start for the queue to grow faster than it drains as soon as a post goes viral — prioritising by qualification score then becomes a genuine necessity, not a nice-to-have.
How to build this yourself — with our stack or any other
The methodology is tool-agnostic, even though the example above runs on GTM Goat:
With GTM Goat: create a table with a post-engager source → add columns for enrichment, qualification and salutation as AI columns → build the sequence in graph mode with condition nodes → leave manual release active until you trust automatic release.
Without GTM Goat, with generic tools: LinkedIn shows you who reacted underneath each of your own posts — that can be exported manually or pulled as a list with a LinkedIn automation tool (e.g. Expandi, Waalaxy, HeyReach). A simple spreadsheet (Google Sheets is enough) with the columns name/company/reaction/qualified-yes-no replaces the AI columns with a manual review — slower, but with identical logic: only approach people who have shown public interest, name that reference in the opener, and never send automatically without a visual check.
The same limit applies in both cases: LinkedIn’s daily cap on connection requests holds regardless of tooling.
Next step
If you would rather have this loop operated than maintain it yourself: take a look at GTM Goat or start a free 4-week trial. For the broader, keyword-based variant across the whole feed, see LinkedIn keyword monitoring.
Data source: Proseller workspace, captured live via a Playwright walkthrough of the product interface (app.cegtec.net/app/proseller, 2026-08-29) — sequence “[Alfred’s posts] Engager · CTA A/B”, table “Post von Alfred — Engager”. Permission to name the client confirmed by Luca. All personal data (names, companies, message texts containing names) in the screenshots has been blurred.